 By Tsuky
A successful AI demonstration can be misleading. An engineer builds a prototype, connects it to a capable model and watches it complete a complicated task. The result looks convincing. Then the application reaches production, usage increases and a different problem emerges. The system may be spending far more money than necessary. Perhaps every request goes to a high-end reasoning model, even when the task is simply classifying an incoming message. Perhaps the same lengthy instructions are processed repeatedly. Or perhaps an agent keeps calling tools after it has already obtained the information it needs. OpenAI's new GPT-6 developer guide addresses these problems directly. Published on October 2, 2026, the document covers the company's model family, reasoning settings, prompt construction, context management and the practical difficulties of building autonomous applications. It is not the announcement of an entirely new model. Instead, OpenAI is explaining how developers should use capabilities that already exist and how to avoid turning powerful AI into an unnecessarily expensive component of ordinary software.
Astra, Sol and Luna represent different engineering choices
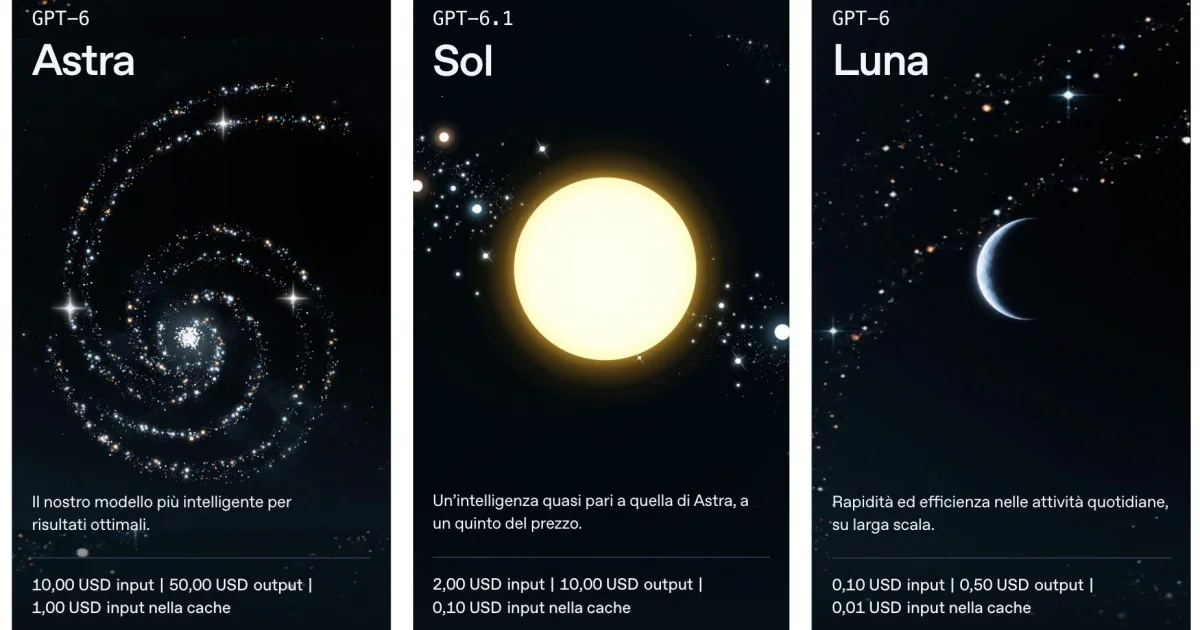
OpenAI organizes its recommendations around three models. GPT-6 Astra is positioned as the most capable option for demanding reasoning tasks. Complex software engineering, difficult research and other high-stakes work may justify its greater computational cost. GPT-6.1 Sol is intended to provide strong capabilities at a substantially lower price. OpenAI highlights coding, research and computer-use workflows among its applications. GPT-6 Luna targets focused, high-volume tasks where cost efficiency matters most. The headline API prices illustrate the difference. Astra costs $10 per million input tokens and $50 per million output tokens. GPT-6.1 Sol costs $2 for input and $10 for output. Luna costs $0.10 for input and $0.50 for output. On those advertised categories, Luna is one-hundredth the price of Astra. That makes a striking comparison, but it does not establish the cost of completing a real workflow. Different models may consume different amounts of reasoning, call different tools or require different numbers of attempts to produce an acceptable result. A low-cost model that fails repeatedly could become more expensive than a stronger model that solves the task immediately. The appropriate comparison is therefore not only price per token. It is price per successfully completed task.
The cheapest model is not necessarily the lowest-cost system
Consider a software service that extracts information from invoices. Most documents may be straightforward. The application needs to identify a date, supplier, amount and a few other fields. A smaller model could be entirely adequate for this work. But some invoices might contain unusual layouts, contradictory information or ambiguous numerical values. A more capable model may handle those cases with fewer errors. The engineering challenge is deciding which workloads require which level of capability. OpenAI recommends evaluating representative tasks across model configurations rather than assuming one model should handle every request. That evaluation should measure accuracy, latency and cost together. It should also include the cost of retries and validation. A system that performs inexpensive inference but requires extensive human correction may deliver little practical saving. Conversely, paying for the most sophisticated reasoning on a routine operation wastes resources if a cheaper alternative meets the same acceptance criteria. Model selection becomes an exercise in allocating intelligence where it produces measurable value.
Reasoning effort adds another dimension to the trade-off
Choosing the right model is only the first decision. The GPT-6 family also provides different reasoning-effort settings, with supported values varying by model. OpenAI recommends using lower effort for routine operations and reserving higher settings for work that genuinely benefits from deeper analysis. A classification request might be handled with relatively little reasoning. A complex debugging task involving several dependencies may benefit from a more intensive approach. The guide also describes cases where particularly demanding work can justify testing the highest supported settings. The important word is testing. Increasing reasoning effort does not automatically improve every response enough to justify the additional time or tokens. Applications should measure whether the change produces a meaningful improvement. OpenAI also describes Fast and Ultrafast processing modes for supported environments. These settings prioritize lower latency and can be useful for interactive applications where response time matters. However, faster processing may have a higher token price. An application generating a real-time interface may benefit from paying more for speed. A nightly batch-processing job may not. The decision depends on the service's requirements rather than the assumption that maximum speed is always preferable.
Prompt caching has become a production architecture decision
One of the guide's most practical recommendations concerns prompt caching. Production applications frequently send the same instructions and reference material across large numbers of requests. A customer-service assistant might repeatedly receive company policies, tool definitions and formatting requirements. An engineering agent may carry the same repository instructions through a long sequence of operations. Processing those shared elements from scratch every time can be wasteful. Prompt caching allows eligible portions of previously processed context to be reused. OpenAI says discounts on cached input can reach up to 95 percent, depending on the model and conditions. To improve cache efficiency, the guide recommends placing stable instructions before the information that changes from one request to the next. Keeping tool definitions consistent can also improve reuse. This is a structural consideration. Two applications using the same model may have different costs because one organizes its context for caching while the other changes large portions of the prompt on every call. The maximum discount should not be confused with a universal reduction in overall spending. Only eligible cached input receives the relevant benefit, while generated output, separate tool charges and other usage categories may still contribute to the bill.
Long-running agents need a smaller working memory
Agents capable of operating for hours face a problem that ordinary short conversations rarely encounter. Their context grows. Every tool response, file inspection, test result and intermediate decision may add information to the conversation. Eventually, maintaining the complete history becomes expensive or inefficient. OpenAI recommends compaction as a way to reduce the amount of context carried forward while retaining the information necessary to continue the task. The goal is not to forget everything that happened earlier. It is to preserve the essential state of the workflow. For a coding agent, that might include which files were changed, which tests were completed, which issues remain and what constraints must still be respected. A full transcript of every intermediate action may be unnecessary. The challenge is deciding what to retain. A poorly constructed summary can remove important context, forcing the model to repeat work or make decisions based on incomplete information. Compaction is therefore not simply a cost-saving switch. It becomes part of the system's reliability design and should be tested accordingly.
OpenAI is telling developers to rethink oversized prompts
Perhaps the most interesting recommendation challenges a habit that developed during earlier generations of AI models. Many engineering teams have accumulated extremely detailed instructions intended to control model behavior. Their prompts may specify every intermediate step, include numerous examples and repeat constraints in several forms. That style emerged partly because older models often required careful guidance to produce reliable results. OpenAI now argues that excessive instruction can sometimes interfere with stronger models. Eric Provencher, from OpenAI's Developer Experience organization, says improved understanding of nuance means overly prescriptive prompts may hinder performance in cases where detailed guidance once helped. The guide recommends defining the objective, intended audience, relevant context, important constraints and completion criteria. Developers should distinguish essential requirements from unnecessary procedural rules. A security boundary should remain explicit. A lengthy ritual describing exactly how to perform a routine analysis may not be necessary. OpenAI specifically encourages teams to revisit their skills and AGENTS.md files. These resources often accumulate guidance over time. Instructions written for an older model may remain in place even when they no longer serve a useful purpose. Cleaning them up can improve consistency and reduce context overhead without requiring a new model or a more expensive reasoning setting.
An autonomous agent needs clear authority, not unlimited freedom
Greater model capability creates an operational question: what should an agent be allowed to do independently? A coding agent might be able to inspect a repository, modify source files and run tests. Those actions are often valuable precisely because they do not require constant human supervision. But unrestricted autonomy would be inappropriate for every task. Deleting production data, changing access permissions or deploying a significant modification can have consequences beyond the immediate development environment. OpenAI recommends establishing clear decision boundaries. Developers should identify safe routine actions that may proceed without approval and define circumstances where the agent must request input. This is different from forcing the system to ask for confirmation before every small step. Excessive approval requirements can undermine the efficiency of automation. The goal is to match the level of autonomy to the risk of the action. The guide also recommends defining completion criteria carefully. An agent that writes a code patch has not necessarily finished the task. It may need to execute tests, inspect the results and fix failures. The definition of done should reflect the actual outcome required, not simply the fact that the agent produced some code.
Asynchronous tools change how agents spend their time
Long-running workflows often depend on external tools. A test suite may take several minutes. A data-processing job might require additional time. An external service may respond slowly. Traditional sequential execution can leave an agent idle during these operations. OpenAI recommends asynchronous tool calling where supported. The agent can continue work that does not depend on a pending result while the external process runs. Once the result is available, the application returns it using the corresponding tool-call identifier. The agent can then incorporate the information before completing dependent work. This distinction matters because concurrency can create mistakes if the system assumes an unfinished operation succeeded. Correct orchestration requires tracking pending tasks and preserving dependencies. The guide also describes mid-turn steering. This capability allows additional instructions to be introduced while an agent is working. A developer might correct a requirement or alter the priority of a task without necessarily discarding all completed work. However, the update does not automatically undo actions already performed. Applications must manage the relationship between new instructions and the existing execution state. The combination of asynchronous calls and steering is intended to make longer workflows more responsive and less wasteful.
Multi-agent delegation is useful only when tasks are genuinely separable
OpenAI also discusses delegation between agents. In supported Responses API environments, GPT-6.1 Sol can assign independent subtasks to other agents and combine their results. The capability is described as being in beta. The underlying idea is straightforward. An engineering project may involve several activities that do not depend directly on each other. One agent could inspect test coverage while another evaluates a different part of a codebase. A coordinating system could then combine the findings and decide what to do next. But parallel execution is not automatically better execution. Tasks that depend heavily on the same files or shared state can create conflicts. Different agents may duplicate work or produce inconsistent assumptions. Delegation also adds communication and coordination costs. The guide's broader principle remains applicable: use additional complexity only when it provides a measurable benefit. A single capable agent may still be the better choice for a task that requires a continuous chain of reasoning.
Computer use extends automation beyond APIs
Some software cannot be controlled effectively through a convenient API. It may require users to interact with a browser, desktop interface or specialized application. OpenAI identifies computer use as a way for supported models to perform such operations. An agent may be able to navigate a website, enter information or inspect the visible result. However, the guide recommends choosing the simplest reliable method for each action. If a direct API can complete the task, it is generally preferable to reproducing the same operation through a sequence of simulated clicks. Computer use becomes useful when the interface itself is the required path. The approach also introduces additional failure modes. Buttons can move, pages can change and visual interpretations can be mistaken. Sensitive actions still require suitable permissions, confirmation rules and output checks. OpenAI mentions technologies including Playwright and PyAutoGUI in the context of building controlled computer-use workflows. The message is not that graphical automation should replace established integrations. It is that developers now have another tool for applications that require interaction with software not designed for machine access.
Production evaluation matters more than a successful demo
The final emphasis of the guide is operational discipline. A prototype can demonstrate that an AI model understands a task. It cannot establish how the system will behave across thousands of different requests, unexpected inputs and external tool failures. OpenAI recommends testing representative workloads before deployment. Teams should measure task success, latency and cost under realistic conditions. They should also decide how they will monitor behavior and manage data. An agent with permissions to modify files or interact with services must be evaluated differently from a model that only produces text. The system needs reliable boundaries and sufficient visibility into its actions. Those requirements may not generate impressive demonstrations, but they often determine whether an application is suitable for production. The guide also reinforces the importance of comparing different configurations rather than treating a model's headline capabilities as a guarantee of better results. Performance depends on the complete workflow.
The most useful GPT-6 upgrade may be better engineering
OpenAI's October 2 publication represents a shift in emphasis. The company's model family now spans a wide range of prices and capabilities. Developers can also adjust reasoning effort, processing speed and the way agents coordinate their work. Those choices create flexibility, but they also make poor architecture decisions more costly. Selecting Astra for everything may waste resources. Selecting Luna for everything may create quality problems that require expensive retries or human intervention. Ignoring caching can increase the price of repeated context. Poorly managed long-running agents may become slow or difficult to control. The guide's strongest argument is that production AI should be evaluated as an entire system. A successful implementation needs the right model, appropriate permissions, reliable tool handling and measurable outcomes. There is no universal configuration that guarantees the best result. The most capable model may be essential for one stage of a workflow and unnecessary for the next. That is the practical meaning of choosing intelligence according to workload. The AI industry will continue competing on raw model capability. But for developers deploying real products, efficiency, reliability and predictable costs are becoming equally important measures of progress.